 Estimatein 1 hourEstimate a projectreply within 1 hour
Articles on software development
Pricing, timelines, technologies and pitfalls — written from our own projects.
Estimatein 1 hourEstimate a projectreply within 1 hourPricing, timelines, technologies and pitfalls — written from our own projects.
Breaking down optical character recognition (OCR) and Tabula technologies to extract structured data from PDFs retrieved from web pages.
Which tool to choose for web scraping in Python: lightweight BeautifulSoup, async httpx, or full-fledged Scrapy framework. Compare use cases and production best practices.
Learn how to build a news aggregation system: connecting RSS feeds and websites, content deduplication methods, classification using…
Automating competitor website change tracking helps you gain an edge. We explore diff algorithms, watchers, and more.
Automated collection of prices and assortment from B2B portals and wholesale catalogs. Supplier comparison, loading into ERP. ESK solutions for procurement departments.
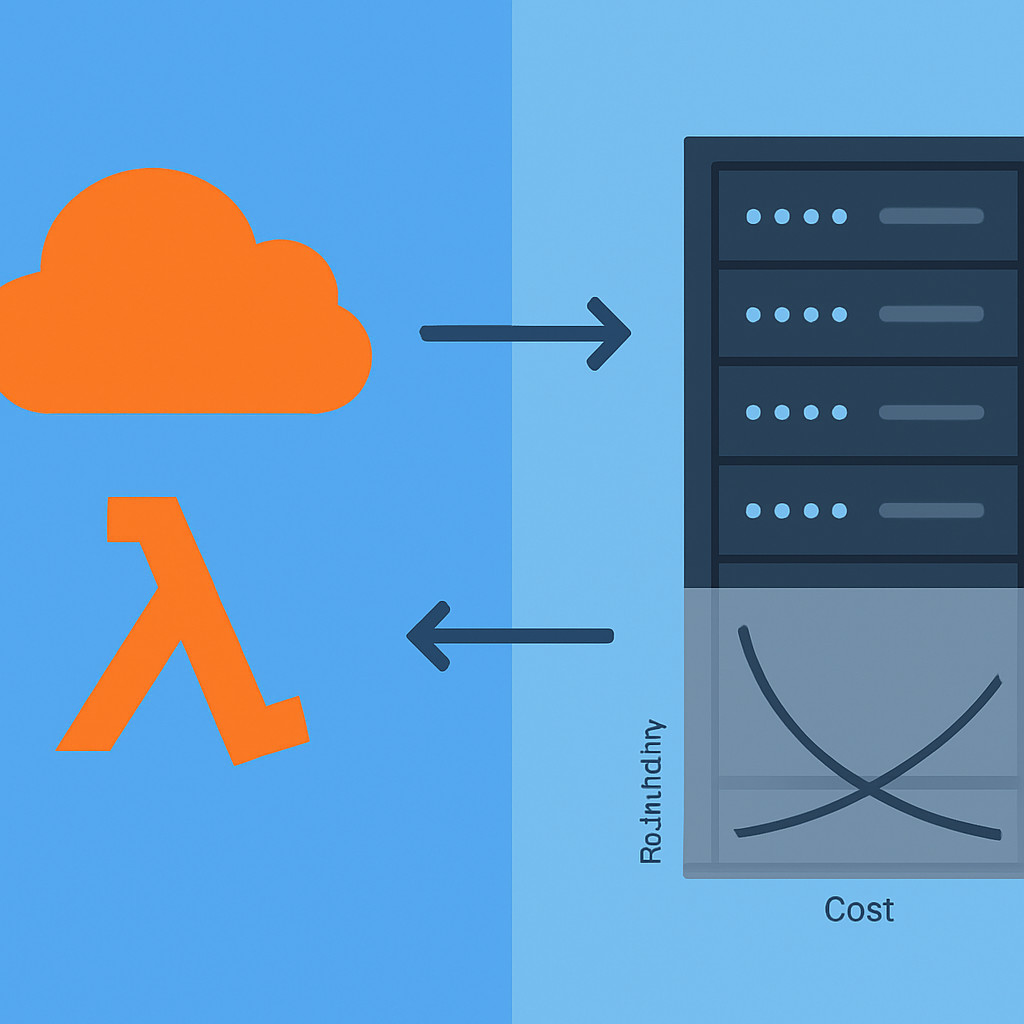
Comparing the economics and reliability of serverless scraping on AWS Lambda with dedicated servers. Cost analysis, scalability, and practical implementation…
Learn to parse positions, snippets, and keyword frequency from SERP: tools overview, methodology, and data integration into reports. Practical insights for SEO.
A comprehensive breakdown of the legal boundaries of web scraping: requirements of robots.txt and terms of service, protection of personal data under Federal Law 152-FZ and GDPR.
We analyze the architecture of horizontally scalable parsers with message queues and workers. Queues based on Redis and RabbitMQ, distributed...
Collect reviews and ratings from Ozon, Wildberries, Yandex.Market for sentiment analysis, reputation monitoring, and BI system integration. Learn more…
Designing ETL processes for parsing data: PostgreSQL storage architecture, queue usage, deduplication, and quality control…
We examine when HTML scraping is cheaper and provides more complete data, and when it's safer to rely on an API. We evaluate total cost of ownership and reliability.
Describe the task in a couple of sentences — we'll name the timeline and price in both models within an hour.